When to Use Jev for Typed, High-Volume Decisions
A practical framework for deciding when Jev’s typed, structured decisions may fit routing, classification and automation workflows—and when an LLM is still the better choice.
Start with the decision, not the model
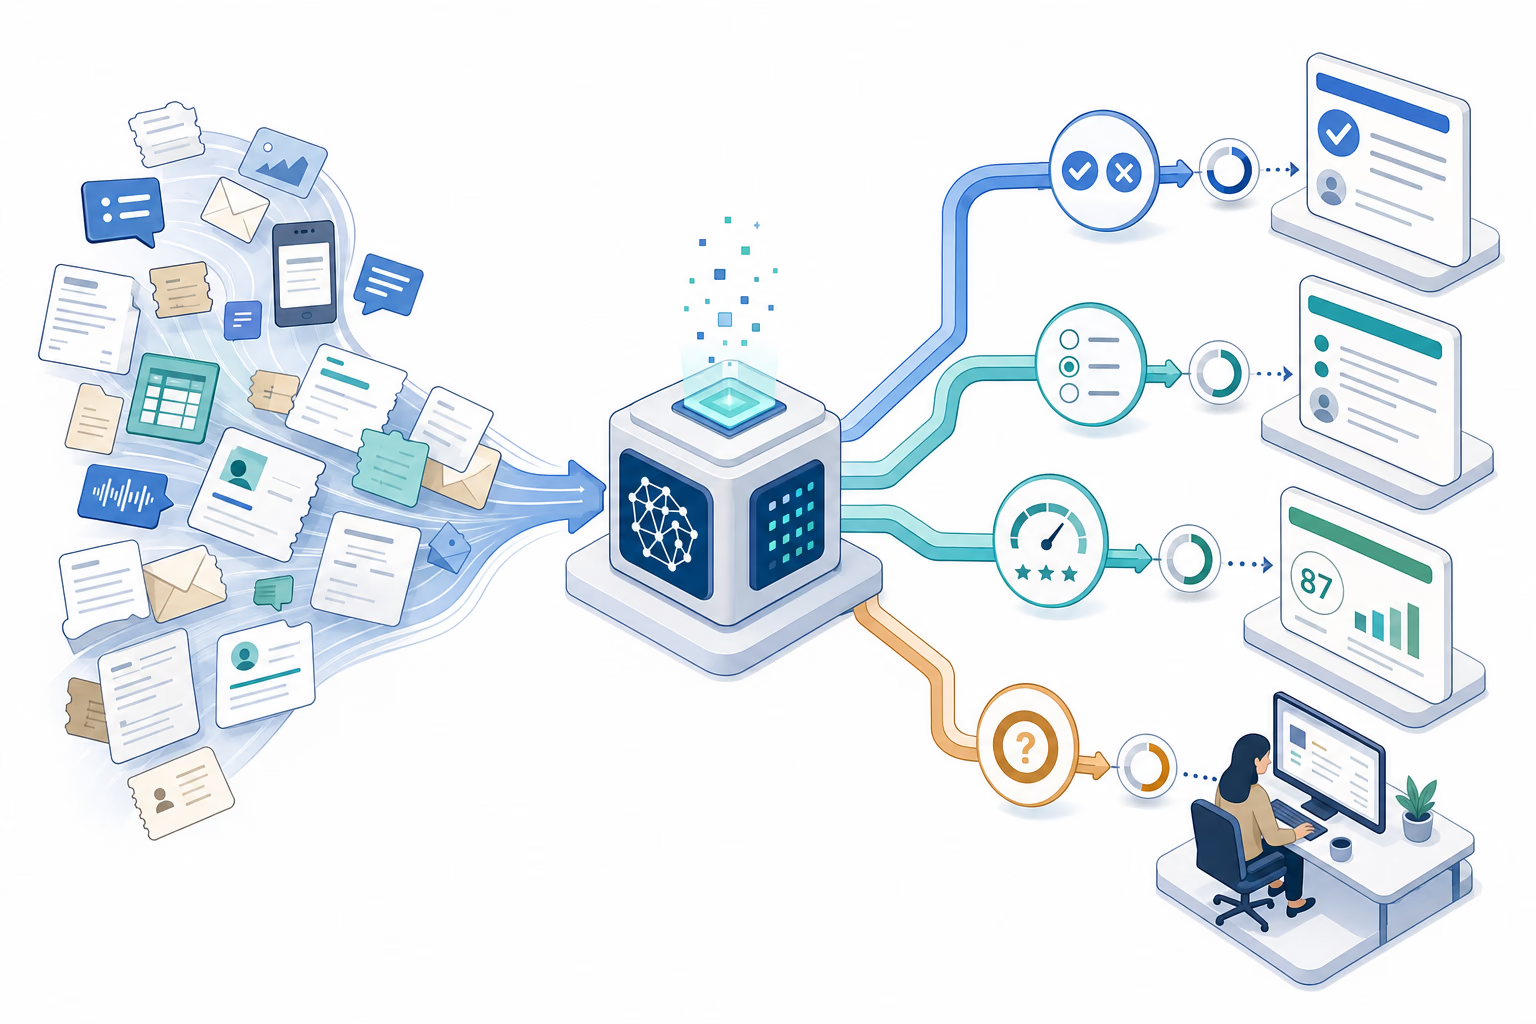
Jev is presented by TypeSafe AI as a model for fast, typed decisions rather than open-ended text generation. In the material supplied for this article, it receives unstructured context plus a predefined set of typed questions, then returns structured answers with probability distributions and confidence scores.
That distinction is the selection rule: consider Jev when the application already knows the possible decisions and needs to make many of them reliably inside a software workflow. Do not choose it merely because a task contains text.
Verification note: the product capabilities, availability, pricing and performance figures below are based on the supplied brief and its linked TypeSafe AI announcement. They have not been independently validated here.
The systems where it is most likely to fit
High-volume routing and triage
A support, operations or intake system may need to decide whether an item should be escalated, which queue should receive it, or whether required information is missing. These are bounded decisions with a known set of outcomes.
A typed decision model can be a good fit when the application can define questions such as:
- Noul: “Does this request require human review?”
- Choice: “Which queue owns this item: billing, technical support, or sales?”
- Score: “How urgent is this request on a 0–100 scale?”
The consuming service should still set thresholds, retain an audit trail and define a fallback route for uncertain cases.
Eligibility, policy and document checks
Jev may also make sense in workflows that classify incoming records against a fixed operational policy: checking whether a submission appears complete, identifying a document category, or flagging a case for manual review.
This is not a reason to let a model make an irreversible legal, financial, employment or medical decision. In high-impact settings, use the output as a triage signal and preserve human review, policy controls and appeal or correction processes where appropriate.
Content and catalogue moderation with fixed labels
If a marketplace, CMS or internal knowledge base already has an approved taxonomy, the task is usually classification rather than writing. A typed choice can route an item to a category, while a boolean can flag whether it needs moderation.
The fit is strongest when labels are stable, definitions are documented and the downstream system can act on a structured value without asking a second model to interpret generated prose.
Product features that need many small judgments
Examples include lead qualification, intent tagging, notification prioritization, duplicate-risk scoring and feature-flag eligibility. These workloads can involve a large number of short, repeated decisions. According to the supplied material, Jev is designed to process its typed questions in parallel rather than generate a response token by token.
That architecture is relevant when latency and inference cost materially affect the product experience or unit economics.
Where a generative LLM remains the better tool
Use an LLM when the result must be original language or extended reasoning: drafting an answer, summarizing a long document for a person, conducting a nuanced conversation, explaining an exception, or working through an unfamiliar problem.
A practical architecture can use both tools. Let a decision model perform the bounded routing step; invoke an LLM only for the branch that needs a natural-language response. This can reduce the number of generative calls, but the savings must be measured in the actual workflow.
A safe pilot procedure
- List the decisions. Write each decision as a boolean, a closed set of options or a numeric score. If the valid answers cannot be defined, the workflow may need an LLM instead.
- Define the action for every output. Specify what the application does for each option, score range and low-confidence result.
- Build a labelled evaluation set. Use representative historical cases, including edge cases and ambiguous inputs. Compare outputs with the expected routing or classification.
- Set confidence thresholds. Send uncertain items to a human queue or a more capable secondary process; do not silently treat every result as final.
- Measure end-to-end economics. Compare latency, error rate, review rate and total cost per completed workflow—not only model token pricing.
- Monitor after release. Track category drift, confidence distributions, overrides and business-impact errors. Update question definitions as policies or inputs change.
How to interpret the “400× savings” claim
The supplied brief attributes savings of up to 400× and substantially faster inference for classification tasks to Jev, alongside input pricing of $0.042 per million tokens and free output tokens. These figures should be treated as vendor claims and workload-dependent, not as a guaranteed outcome.
A fair comparison includes the baseline LLM, prompt size, retry and parsing overhead, validation logic, traffic shape, human-review cost and the error cost of a wrong decision. A typed output can eliminate some formatting and parsing work, but it does not eliminate the need to test semantic correctness.
Decision checklist
Jev is worth evaluating when the answer to most of these questions is yes:
- Is the desired output a finite, typed decision rather than prose?
- Can the business define the options and the action for each one?
- Is the workflow frequent enough for speed or cost to matter?
- Can low-confidence cases be routed safely?
- Do you have representative data to evaluate accuracy before automation?
If not, begin with a generative model, conventional rules, or a hybrid workflow. The right choice is not the model with the largest advertised multiplier; it is the one that delivers acceptable decisions at a measured cost and risk level for the system being built.
Source and limitations
The description of Jev as a “System One Model,” its typed primitives, and the vendor-reported performance and pricing figures are drawn from the information supplied with this request and the linked TypeSafe AI announcement: Introducing System One Models and Jev. The additional numbered references in the brief were not provided as accessible source URLs. This article therefore does not independently confirm launch timing, third-party platform support, benchmarks, pricing or production availability.